

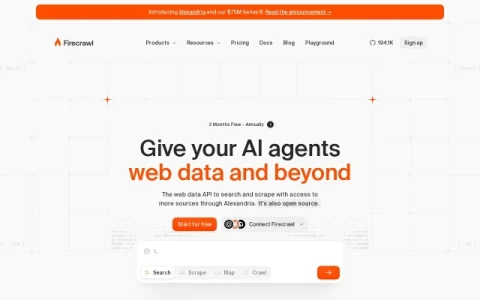
Firecrawl positions itself as the infrastructure layer that helps AI find, read, and act on the live web. Rather than a consumer-facing app, it is an API product aimed at developers who need reliable web data piped into agents, retrieval pipelines, or other AI systems.
The core toolkit covers four operations: Search returns full content from web results, Scrape converts individual pages into Markdown, JSON, or screenshots, Map discovers URLs on a site, and Crawl traverses sites at scale. A newer Interact capability lets you scrape a page and then act on it through AI prompts or code. The service is also open source, and code samples are provided for Python, Node.js, cURL, and CLI.
It is built for AI engineers, data teams, and product developers who need fresh web content without maintaining their own scraping stack. The site reports adoption by more than 150,000 companies, and a free starting tier is advertised alongside annual plans offering two months free.
A practical approach is to begin with the free tier and the Playground to test scraping quality on your target sites, then move to Crawl or Map for broader coverage. Teams with strict data-handling requirements should review the open-source option and documentation before committing to production volumes.

评论与评分
0还没有评论,来写下第一条评价吧。