
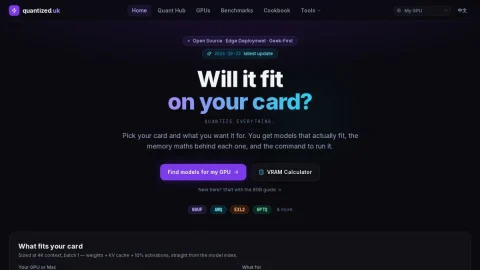
quantized.uk is a reference site built around a single question: will this local LLM actually run on the graphics card I own? Rather than starting from model pages, it starts from hardware, letting you pick a specific GPU or Apple Silicon chip and then showing which entries in its index of 117 quantized models fit within that memory budget.
The core output is a fit table. For each model you see whether it fits, at which quantization level it fits, how much VRAM remains spare, and the command needed to run it. The GPU list is unusually broad for a hobbyist resource, spanning consumer RTX 50/40/30 cards, workstation and datacenter parts like the A100, L40S, A40 and H100, plus a wide range of Mac M-series configurations from 8GB up to 512GB.
It suits people running local inference on their own hardware: hobbyists deciding what to download, buyers checking whether a card is worth upgrading to, and Mac users who want to know how far unified memory stretches. Anyone comparing a 12GB and 16GB card for LLM work will find the spare-VRAM column more useful than raw benchmark charts.
Use it as a pre-download filter. Pick your exact card, note the highest quant level that fits with comfortable headroom, then copy the run command. Treat results as estimates rather than guarantees, since real usage depends on context length and runtime overhead. The site also links out to a quant hub, benchmarks, cookbook and tools sections for further reading.

评论与评分
0还没有评论,来写下第一条评价吧。