
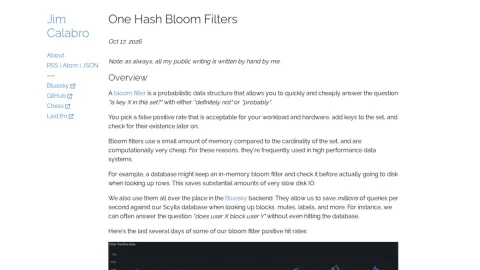
This page is a single technical essay on calabro.io, the personal site of Jim Calabro. Rather than a product or service, it presents a written exploration of one-hash bloom filters, published as part of the author’s public writing. The framing is practical: it starts from what a bloom filter is and why high-performance data systems rely on them.
The core of the article explains the standard bloom filter contract, where a lookup returns either “definitely not” or “probably” in the set, with a false positive rate chosen to fit the workload and hardware. It then moves to the one-hash variant and the memory and computational savings it can offer compared with conventional multi-hash designs.
Production examples anchor the discussion. The author describes using bloom filters throughout the Bluesky backend, where they prevent millions of queries per second from reaching the Scylla database when looking up blocks, mutes, and labels. A concrete case is answering whether one user blocks another without touching the database at all.
The intended audience is backend and systems engineers who already understand probabilistic data structures and want to see how they are deployed at scale. Readers looking for introductory tutorials or runnable code samples should look elsewhere. The best use is as a short, focused read alongside the author’s other posts, which are linked through the site’s RSS, Atom, and JSON feeds.

评论与评分
0还没有评论,来写下第一条评价吧。