

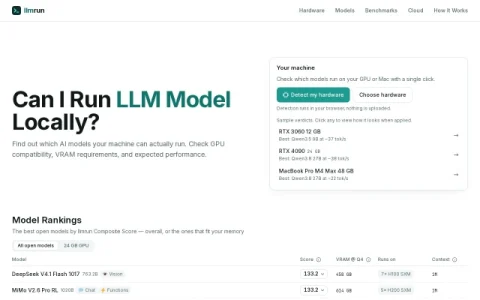
llmrun is a hardware compatibility checker for people who want to run large language models locally. Instead of guessing whether a model will fit, you pick a model and a machine and get a practical verdict on whether it can run, at what quantization level, and roughly how fast.
The site centers on three things: a hardware checker that detects your GPU or Mac in the browser, a model database with VRAM requirements at different quantization levels, and rankings that sort open models by a composite score while filtering to those that fit your available memory. Sample verdicts show expected throughput, such as a 9B model at around 37 tokens per second on an RTX 3060 12 GB.
It suits local-AI hobbyists, developers choosing hardware, and anyone comparing a laptop or desktop purchase against the models they want to run. Because detection happens client-side, nothing about your machine is uploaded, which makes quick checks low-risk.
Use it before downloading a model to avoid wasted bandwidth, and cross-check borderline cases against real-world reports since estimates depend on quantization, context length, and runtime. Treat the rankings as a shortlist rather than a final answer.
In short, llmrun answers the practical question of what your machine can actually handle before you commit to a download or a hardware upgrade.

评论与评分
0还没有评论,来写下第一条评价吧。