
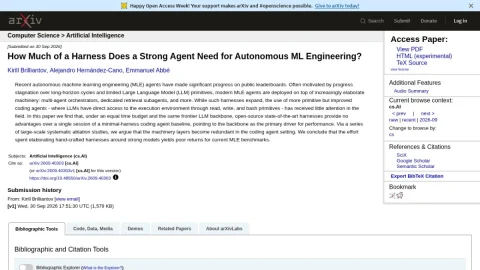
arXiv.org is a widely used open-access preprint server operated by Cornell University. It hosts scholarly articles in physics, mathematics, computer science, quantitative biology, statistics, and related areas, allowing authors to share results before or alongside journal publication. The site is a primary destination for researchers who want to track new work quickly.
The core function of arXiv is straightforward: authors submit papers, and readers browse or search by subject, date, or identifier. Each paper has an abstract page with metadata, version history, and links to PDF and experimental HTML versions. Subject classifications and listing pages help users follow specific areas such as Artificial Intelligence, while identifiers like arXiv:2609.40303 provide stable references.
The site is aimed at academic researchers, graduate students, and industry practitioners in technical fields. It is also useful for journalists and curious readers who want direct access to primary sources. Because papers are preprints, quality varies, and readers should check whether a version has been peer-reviewed or published elsewhere.
For effective use, search by title, author, or arXiv ID, and check the submission date and version history to see how a paper has evolved. Use the abstract page to judge relevance before downloading the PDF, and cite the arXiv identifier when referencing a preprint. Overall, arXiv remains an efficient and essential entry point to current research literature.

评论与评分
0还没有评论,来写下第一条评价吧。