
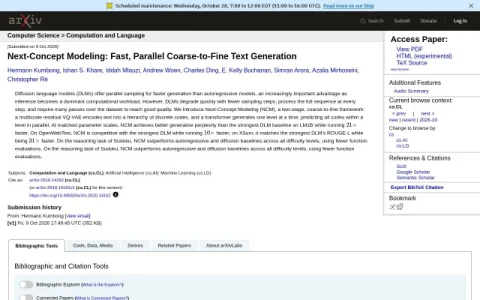
arXiv is a preprint server operated by Cornell University that hosts scientific papers across computer science, physics, mathematics, statistics, and quantitative biology. Each entry is an abstract page with author lists, submission dates, and links to full-text PDFs, making it a primary channel for research that has not yet completed formal peer review.
The core value lies in early and open access. Papers are indexed by subject area and identifier, and the abstract page provides citation details, version history, and related formats including experimental HTML rendering. Readers can browse by category or search by title, author, and keyword without creating an account.
It is aimed at academic researchers, graduate students, and industry practitioners who need to follow developments before journal publication. Because submissions are not vetted for correctness, the site rewards readers who can evaluate methods and results critically rather than treating every preprint as established fact.
A practical approach is to use the abstract page as a screening layer: read the abstract and skim the PDF before committing time to a full paper, and check version dates since preprints are often revised. For this particular paper, the page covers a text-generation method called Next-Concept Modeling, but the same workflow applies across the repository.

评论与评分
0还没有评论,来写下第一条评价吧。