
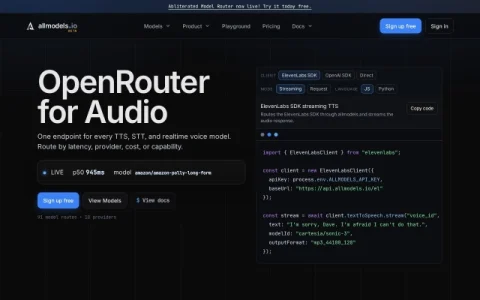
AllModels positions itself as an audio-focused model router, described on its homepage as “OpenRouter for Audio.” Instead of committing to a single speech vendor, developers send requests to one endpoint and let the platform dispatch them across a catalog of TTS, STT, and speech-to-speech models supplied by many providers.
The core offering is schema normalization: each provider’s API is translated into a common request and response format, so switching from one voice model to another does not require rewriting client code. Routing can be tuned by latency, provider, cost, or capability, and the site advertises live p50 and p95 latency figures alongside a browsable model list covering dozens of routes and providers.
A separate Abliterated Model Router extends the same fallback approach to uncensored LLMs, and a playground plus documentation for both audio and LLM APIs round out the product. This makes the platform most relevant to backend and ML engineers building voice agents, transcription pipelines, or realtime conversational interfaces.
Before integrating, check the pricing page and confirm which providers and models are currently available, since the catalog and latency numbers change over time. Teams should also verify data-handling terms for each upstream provider. Overall, AllModels is a practical abstraction layer for teams that expect to experiment with multiple voice models rather than standardize on one.

评论与评分
0还没有评论,来写下第一条评价吧。