
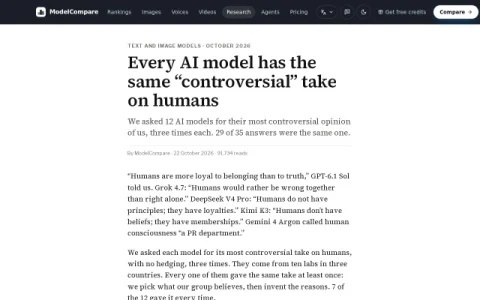
ModelCompare positions itself as a place to compare text and image models across providers. Rather than acting as a plain directory, it runs the same prompts through multiple models and reports what came back, so readers can see how different systems respond to identical input.
The site’s core content is comparative testing. In the published experiment, 12 models from ten labs in three countries were each asked three times for their most controversial opinion about humans, and 29 of 35 answers converged on the same claim about belonging versus truth. Individual model answers are presented so readers can inspect the wording themselves.
It suits people evaluating AI models for research, writing, or product decisions who want behavioral evidence rather than spec sheets. Readers comparing model tone, consistency, and framing will get the most from it.
A practical suggestion is to read the methodology and sample size before drawing conclusions, since a single prompt set reflects only one dimension of model behavior. Use the experiments as a starting point and pair them with your own tests.
Overall, ModelCompare works best as a source of concrete, reproducible model comparisons rather than a definitive ranking.

Comments & Ratings
0No comments yet. Be the first to review.