
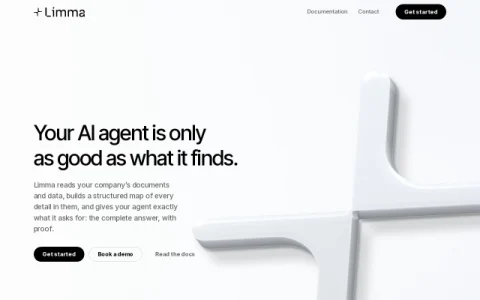
Limma positions itself as a single MCP server for all of a company’s data. Rather than treating retrieval as a reading aid, it treats it as an answering problem: the agent should receive the records that satisfy a question, not merely passages that resemble it. The product reads documents and data sources in full and constructs a structured map of the details inside them, which the agent can then query.
The core argument is that chunking and similarity search were designed for reading, not for completeness. Fragments are split before anyone knows what will be asked, facts spanning two fragments survive in neither, and the number of returned slices stays fixed as data grows. Limma addresses each of these by mapping meaning at the record level and returning the complete answer together with proof of where it came from.
It is aimed at teams running AI agents over internal knowledge: engineering and data teams wiring agents to company documents, and organizations where an incomplete answer carries real cost. Because it connects to existing sources and indexes them, it fits companies that already have a body of documents and data worth mapping rather than individuals experimenting with a single file.
Adoption means connecting your sources, letting Limma build the map, and then pointing your agent at the MCP server instead of a vector store. Expect an integration step before results appear. The site offers a demo booking and documentation for evaluating fit, and the mechanism is

Comments & Ratings
0No comments yet. Be the first to review.