
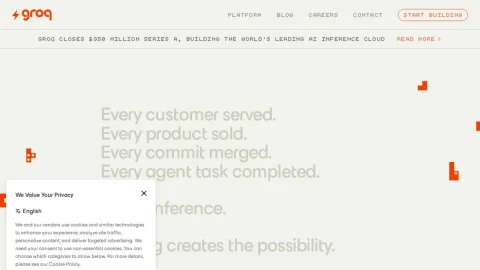
Groq positions itself as a neocloud focused specifically on AI inference rather than training. The company argues that while training creates possibility, inference creates value, and that inference is becoming the bottleneck as AI usage grows. Its platform combines infrastructure, inference, and control in one integrated stack.
The core of the offering is Groq’s custom LPU chip, now complemented by LPX working alongside NVIDIA’s next-generation GPUs. This combination is designed to deliver fast inference without forcing a choice between speed and affordability. Groq reports building hundreds of megawatts of capacity to support scale.
The platform targets developers and enterprises running large language models in production, including agent tasks and high-volume token generation. Millions of developers already run trillions of tokens on Groq weekly, suggesting traction among teams with demanding inference workloads.
For evaluation, start with the platform and blog to understand the hardware and pricing model, then test representative workloads to compare latency and cost against existing providers. Teams should confirm regional capacity and integration requirements before committing production traffic.
In short, Groq is a specialized inference cloud for teams that treat inference speed and cost as core infrastructure decisions.

Comments & Ratings
0No comments yet. Be the first to review.