
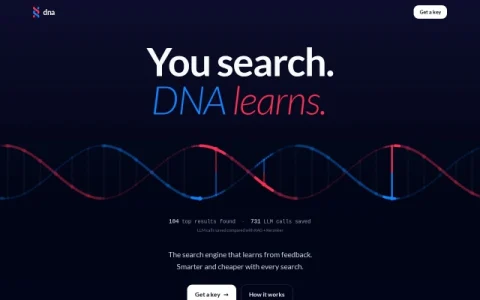
Hashgrid DNA is positioned as a feedback-driven search engine rather than a hosted vector database. You bring your own items and generate one embedding per item with any model you like, then query through a simple HTTP API. The system proposes results between your searches and your items, and results confirmed by feedback are reinforced over time.
The core loop is deliberately minimal: send embeddings, run a search, and return a score when you have one. Scoring can come from an LLM, a small model, or your users’ clicks. DNA trains on its own side, so you do not host or tune a model yourself, and the page advertises savings in LLM calls compared with a RAG plus reranker setup.
It fits developers and product teams that already have a catalog of nodes such as products, documents, tools, or people, along with some source of relevance feedback. Because any embedding model works and the integration is a few API calls, it can slot into existing retrieval pipelines without a migration.
A practical approach is to start with a small item set and a single feedback signal, watch the top-results and LLM-calls-saved counters, then expand scoring sources once relevance stabilizes. Access requires an API key, so evaluate it against your current retrieval stack before committing.

Comments & Ratings
0No comments yet. Be the first to review.