
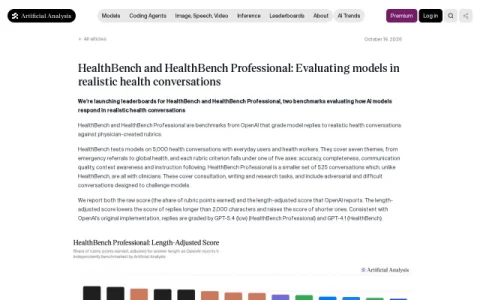
Artificial Analysis has added leaderboards for two OpenAI benchmarks that assess how AI models handle realistic health conversations. Rather than measuring medical knowledge in isolation, the benchmarks grade actual model replies against rubrics written by physicians, making the results closer to what users would encounter in practice.
HealthBench draws on 5,000 conversations with everyday users and health workers across seven themes, ranging from emergency referrals to global health. Each rubric criterion maps to one of five axes: accuracy, completeness, communication quality, context awareness and instruction following. HealthBench Professional is a smaller set of 525 conversations, all with clinicians, covering consultation, writing and research tasks, and includes adversarial and difficult exchanges designed to challenge models.
The leaderboards report both the raw score, meaning the share of rubric points earned, and response length. Showing length alongside score matters because longer answers can accumulate rubric points, so readers can judge whether a high score reflects substance or verbosity.
These leaderboards suit teams building or procuring health-related AI features, researchers comparing model behavior on clinical communication, and anyone who wants a rubric-based view of model performance beyond generic benchmarks. When using the results, check both score and length, and note that HealthBench and Professional measure different audiences and should not be tr
Comments & Ratings
0No comments yet. Be the first to review.