
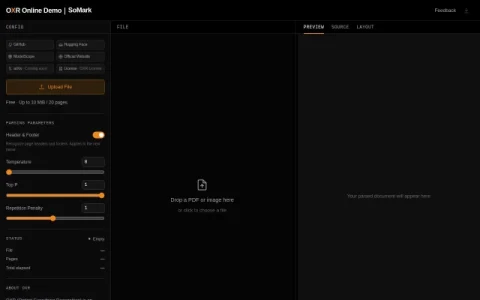
OXR stands for Optical Everything Recognition, an open-source model released by the SoMark team. This page is its free online demo, letting visitors run the model on their own documents without installing anything. The stated goal is turning PDFs and document images into agent-friendly data, delivered as Markdown or JSON with layout coordinates preserved.
The demo accepts a PDF or image upload of up to 10 MiB or 20 pages and returns a parsed result alongside a source preview and layout view. Before parsing, users can toggle header and footer recognition and adjust sampling parameters including temperature, top-p and repetition penalty. A status panel reports queue wait, processing time and total elapsed time, and a retry option is available when a run fails.
The project positions itself on benchmark performance: 1.3B parameters, first place on olmOCR-Bench, OmniDocBench and DocParsingBench, and a recursive self-improvement loop used during post-training. Links point to GitHub, Hugging Face, ModelScope, the official site and an arXiv paper marked as coming soon, with an OXR License governing use.
This demo suits developers evaluating document parsing for RAG or agent pipelines, researchers comparing layout-aware extraction, and teams deciding whether to self-host the open-source model. Anyone needing bulk or automated processing should plan a local deployment instead of relying on the web demo.
To get useful results, upload a representative sample rather than a trivial one
Comments & Ratings
0No comments yet. Be the first to review.