
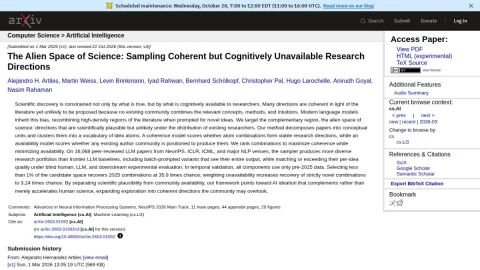
arXiv is a nonprofit preprint server operated by Cornell University, hosting scholarly manuscripts across computer science, physics, mathematics, statistics, and adjacent disciplines. Papers appear as numbered identifiers such as arXiv:2603.01092, with submission and revision dates listed so readers can track how a work evolved.
Each abstract page provides the title, author list, abstract, and links to PDF and experimental HTML versions, plus subject classification like Computer Science > Artificial Intelligence. Version history and DOI-style identifiers make citing straightforward, and search plus advanced search help locate related work.
The site serves graduate students, faculty, and industry researchers who need early results before journal or conference publication, as well as journalists and engineers monitoring fast-moving fields. Readers should treat content as unreviewed and verify claims against published versions.
A practical approach is to use the abstract to judge relevance, then open the PDF for methods and figures, and check later versions for corrections. Following the listed subject categories helps surface adjacent papers that keyword search may miss.
Comments & Ratings
0No comments yet. Be the first to review.